Citiverse è uno spazio aperto a tutte le comunità. Se vuoi aprire un gruppo locale o una sezione per la tua organizzazione, puoi contattare gli amministratori: pagina dei contatti.
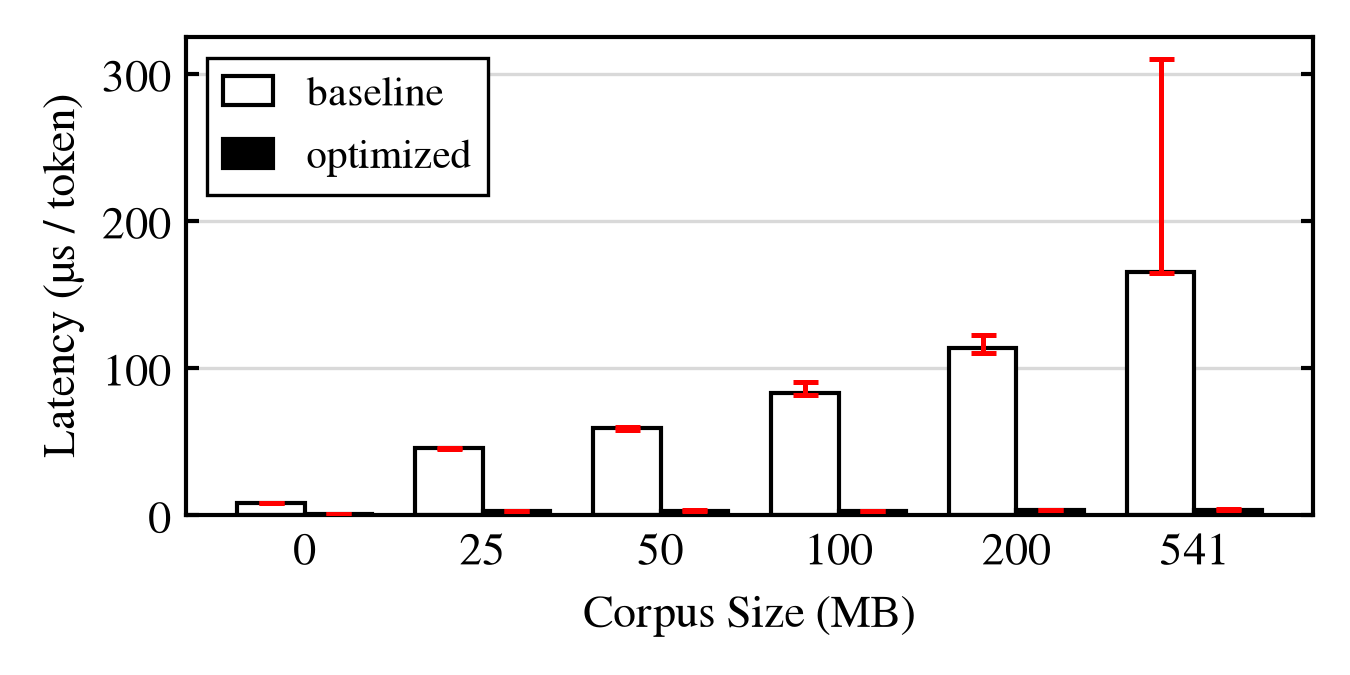
42x Faster Prompt Lookup Drafting in llama.cpp
-
This post did not contain any content.
42x Faster Prompt Lookup Drafting in llama.cpp
Four changes to the n-gram caches of llama.cpp make drafting for prompt lookup decoding up to 41.6x faster per drafted token, load the static cache up to 23.5x faster, and lower peak memory up to 2.65x.
(jadidbourbaki.github.io)

Ciao! Sembra che tu sia interessato a questa conversazione, ma non hai ancora un account.
Stanco di dover scorrere gli stessi post a ogni visita? Quando registri un account, tornerai sempre esattamente dove eri rimasto e potrai scegliere di essere avvisato delle nuove risposte (tramite email o notifica push). Potrai anche salvare segnalibri e votare i post per mostrare il tuo apprezzamento agli altri membri della comunità.
Con il tuo contributo, questo post potrebbe essere ancora migliore 💗
Registrati Accedi


 Citiverse è un progetto che si basa su NodeBB ed è federato! | Categorie federate | Chat | 📱 Installa web app o APK | 🧡 Donazioni | Privacy Policy